
We gave the same one-line request to two models. One finished in 1 minute 42 seconds for 14 cents. The other took almost 5 minutes and cost 65 cents. The videos they produced looked quite different.
The fast one was Gemini 4 Argon, which Google made generally available on October 13. We wanted to see how far Argon gets when you ask it to write code for a motion graphics video, so we gave the same request to three other models and compared.
This post covers:
- What Argon is
- Pricing and where you can use it
- What early users reported
- Our own comparison with the same request
- Summary: when Argon makes sense
How to read the numbers. [Official] means material published by Google. [Community] means results other developers posted on X and elsewhere (we did not reproduce them). [Measured] means numbers we got by running the same request ourselves.
1. What is Argon?
- A new model made generally available on October 13, 2026, and the first model in the Gemini 4 family [Official] (Google blog).
- It reads text, images, video, audio and PDFs. A token is a small piece of text; Argon handles about 1 million tokens (1,048,576) of input and output combined in one go [Official] (model docs).
- But it only outputs text. It cannot draw video directly, so to get a video you have to ask it to write code that describes the motion on screen.
Google's benchmark table
Google published a table comparing Argon with three competitors (GPT-6 Astra, Claude Fable 5.1, Claude Opus 5.5). Argon is the sole leader in 13 of the 19 rows [Official] (DeepMind model page).
| Benchmark | What it measures | Argon | Leader |
|---|---|---|---|
| DeepSWE v1.1 | Multi-step development tasks in real code projects | 77.9% | Argon |
| Terminal-bench 4.0 | Finishing a job end to end with shell commands | 57.4% (lowest of the four) | Opus 5.5 66.4% |
Read the notes under the table too. Argon's scores were measured at the highest thinking setting, while the other models' scores are what each company reported. The product default is "medium" [Official] (evaluation methodology).
A detail you only see at the end
The Google Developers blog has a case study titled "optimizing a 200,000-line Python codebase overnight." Read to the end and you find that a human wrote a rulebook first, and only 2 of Argon's 6 optimization proposals were accepted [Official] (Google Developers blog).
2. Pricing and where you can use it
- Per 1 million tokens: $2 input, $10 output. Input is the text you send; output is the text the model writes, and tokens the model spends thinking also count as output [Official] (pricing page).
- This is introductory pricing through November 30, 2026. From December 1 it doubles to $4 input and $20 output, the same as Opus 5.5 [Official].
- At today's prices, GPT-6.1 Sol and Sonnet 5.5, which we also tested, are the same $2 / $10 (OpenRouter Sol page, Opus 5.5 page).
- The pricing page says Argon is not available on the free tier or the Google AI Pro plan [Official].
3. What early users reported
Right after launch, X was full of speed and price comparisons. All numbers below are what the posters reported, each from a single run. [Community]
| Poster | Task | Opus 5.5 | Argon | Poster's verdict |
|---|---|---|---|---|
| @EnvolDev | 3D space train scene | 1h 53m, $23.46 | 4m 20s, $3.40 | Opus ahead on detail: clouds, locomotive structure, camera work |
| @bridgemindai | Lava lamp | 9m 35s, $1.27 | under 2m, $0.18 | Impressive |
| @vib3coded | Ship in a bottle | $12.06 | $0.19 | Opus much better on glass and water detail |
| @notjazii | Same prompt, highest thinking for both | 15m, $8.20 | 13m, $1.20 | Nearly identical results (different tools were used) |
On YouTube, BridgeMind had Argon make a 30-second launch video on a livestream, put it next to the one Opus 5.5 made for the same task, and said Opus was better on taste, transitions and music (BridgeMind livestream, from about 47:50). [Community]
One caveat: many English-language reviewers had early access from Google before launch. Even so, none of the posts or videos we looked at said Argon beat Opus 5.5 overall.
4. Our comparison with the same request
Setup
- Task: a 20-second motion graphics promo for two of my courses (an intro to Codex and an intro to building AI agents)
- Method: each model wrote the motion as HTML, CSS and GSAP code, and we rendered that code to a 1920×1080 video. We supplied clay-character illustrations as material.
- Two requests: a one-line request, and a detailed request spelling out the goal, the audience, the scene flow and camera moves
- Four models: Gemini 4 Argon, GPT-6.1 Sol, Sonnet 5.5, Opus 5.5. All called through the API (via OpenRouter); time, tokens and cost are the usage values from the API responses. These are not results from the Gemini app or Antigravity.
- One run per condition.
At first, every model produced something that looked like slides: alternating text cards. So we stated clearly "motion graphics, not slides," provided the character art, and compared that second round. Each image below shows 12 frames sampled at even intervals from one video.
One-line request
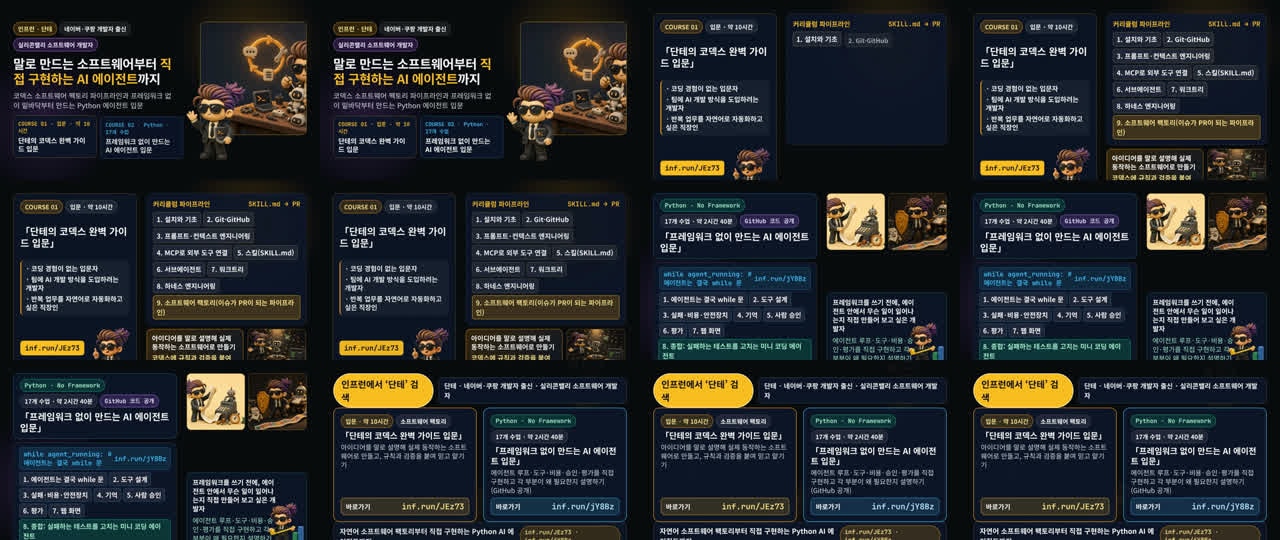
Argon finished in 1m 42s for 14 cents. But the result was a run of text boxes, the bottom text was cut off, and the screen froze for more than 3 seconds in one stretch. [Measured]
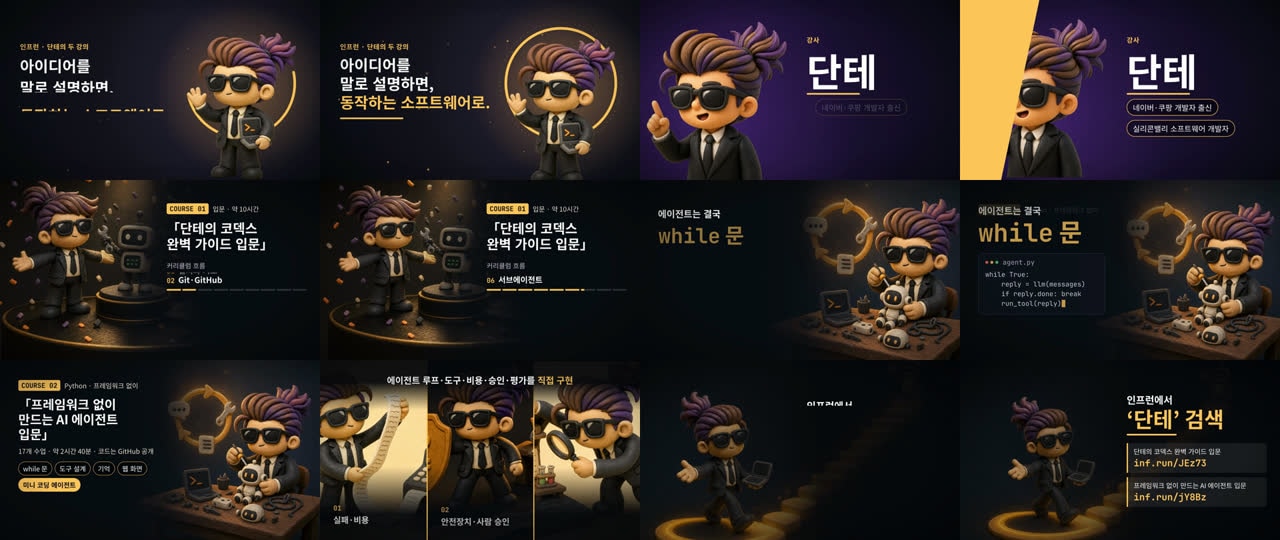
Opus 5.5 made a video where the character moves between scenes from the same one-line request. It took 4m 55s and 65 cents, and to my eye it looked the most like a real video of the four. [Measured]
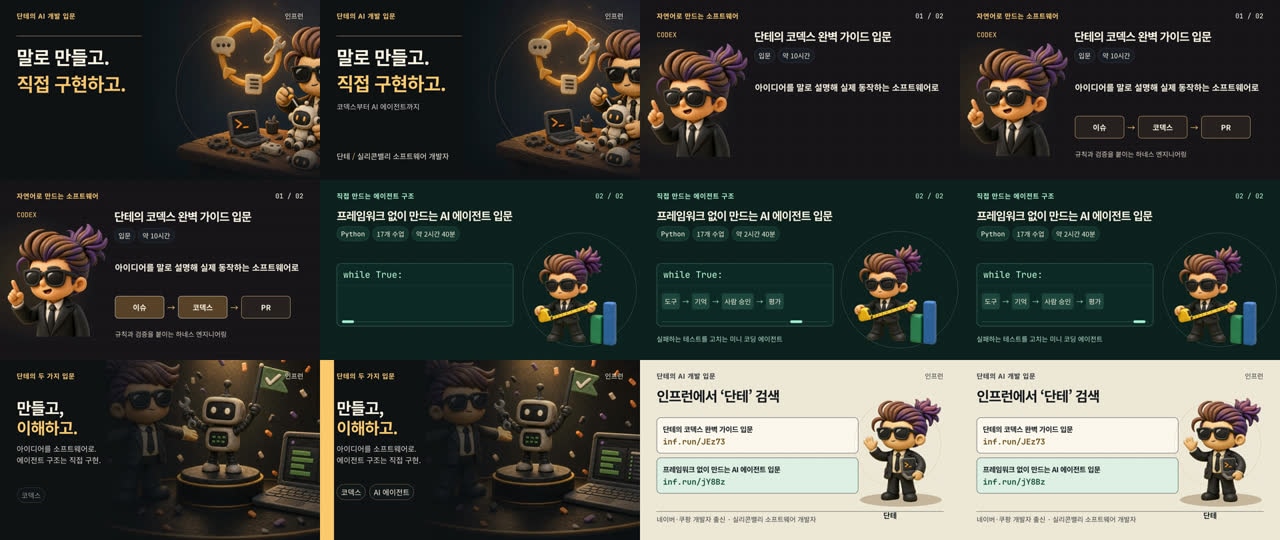
Sol took 1m 45s, 7 cents. [Measured]
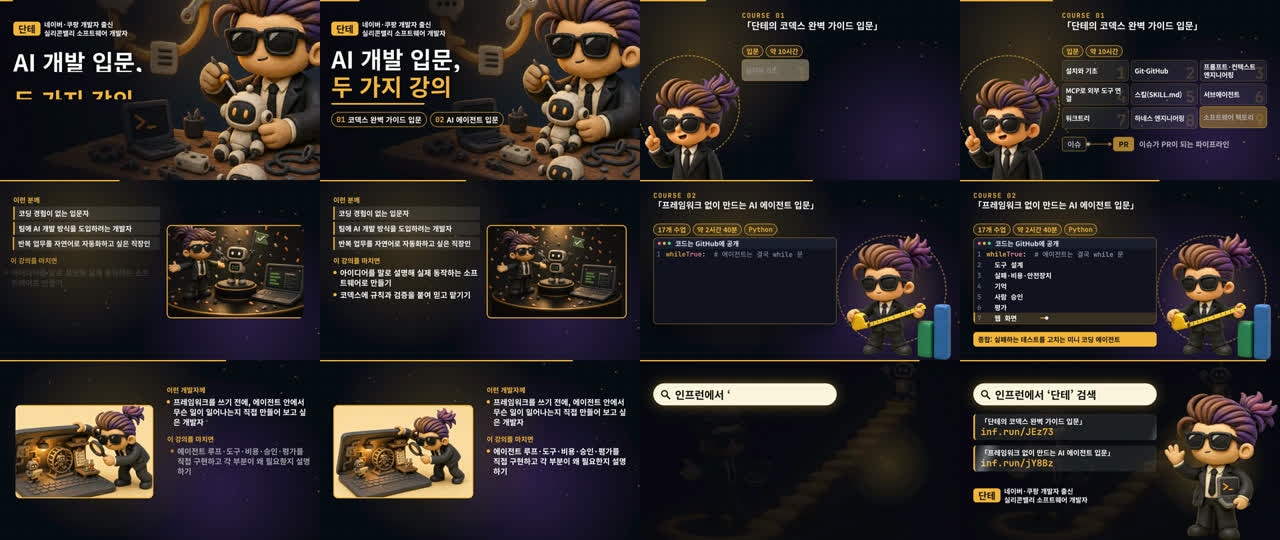
Sonnet 5.5 took 5m 25s, 45 cents. [Measured]
Detailed request
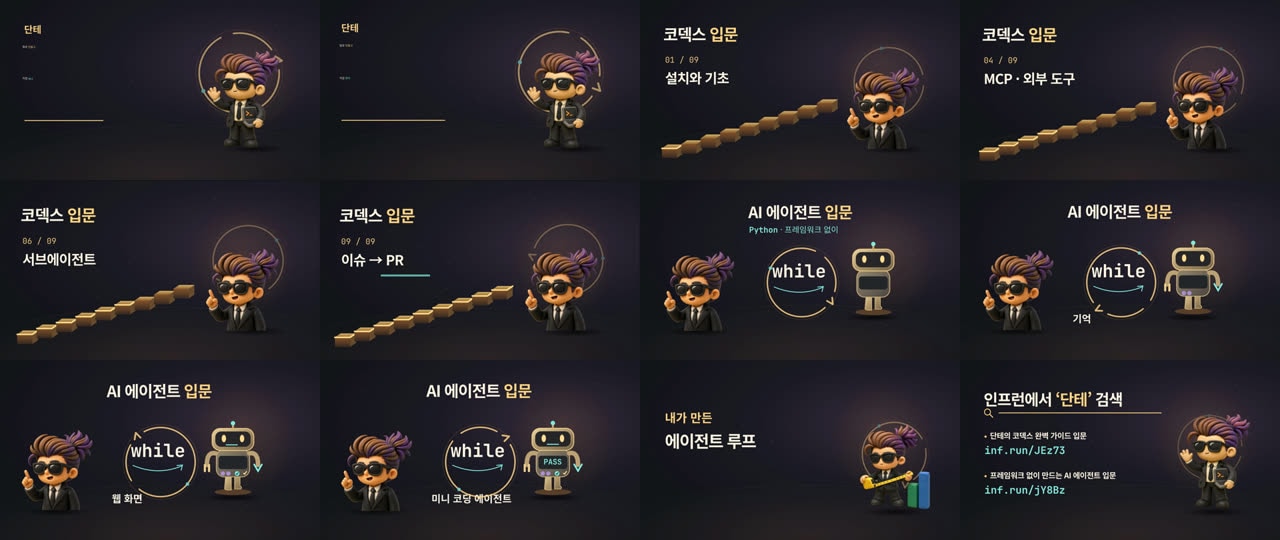
Sol made a character climbing a staircase and a while-loop scene in 2m 34s for 10 cents. [Measured]
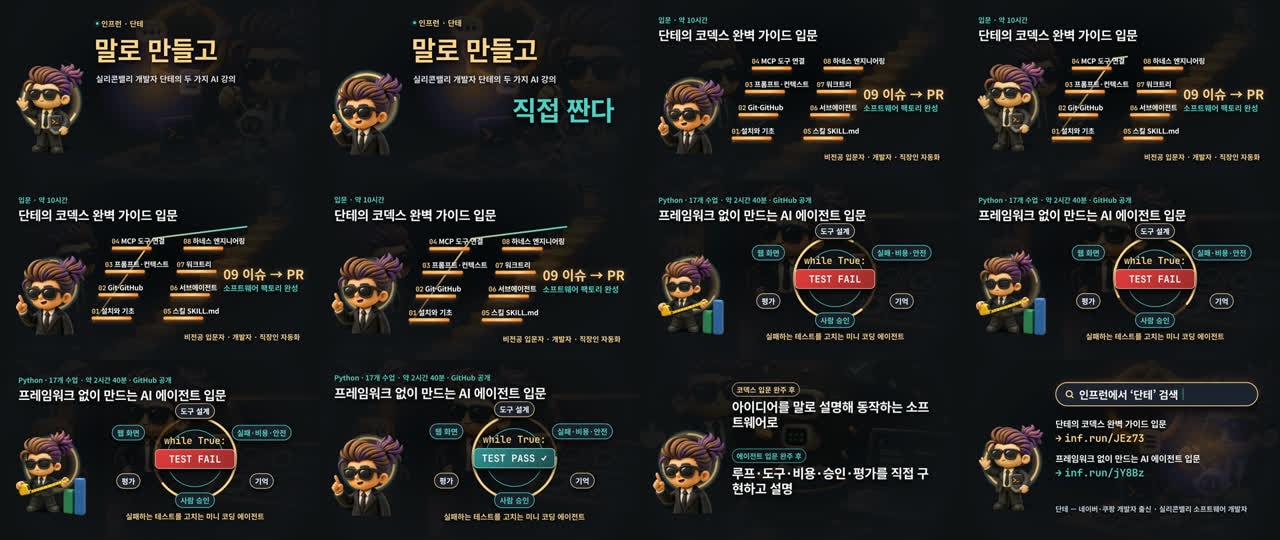
Argon's screens were much tidier, but closer to a text-heavy infographic. With this request, automated checks failed and we had to ask it to fix things twice; the three calls together took 5m 3s and 53 cents. [Measured]
Opus and Sonnet used up their entire output limit on thinking for the detailed request, so no video code came back. [Measured]
At a glance
| Model | One-line request | Detailed request |
|---|---|---|
| Gemini 4 Argon | 1m 42s · $0.14 | 5m 3s · $0.53 (3 calls) |
| GPT-6.1 Sol | 1m 45s · $0.07 | 2m 34s · $0.10 |
| Sonnet 5.5 | 5m 25s · $0.45 | No code (output limit used up) |
| Opus 5.5 | 4m 55s · $0.65 | No code (output limit used up) |
Same price, so why did Argon cost twice as much as Sol?
Argon and Sol have the same price today. But on the one-line request, Argon wrote about 13,700 output tokens and Sol about 6,500. Argon wrote roughly twice as much code, so it cost roughly twice as much. [Measured]
5. Summary
- In our runs, Argon was about three times faster and more than three times cheaper than Opus and Sonnet. The claim that speed and price are its strengths held up.
- But Sol, at the same price, was cheaper and about as fast, and on the detailed request I thought its video was better.
- Opus and Sol led on polish. Argon got noticeably better when the request was detailed.
- Other people's results pointed the same way: Argon for speed and price, Opus for detail and polish.
- On Korean: Argon copied the course names and links we gave it onto the screen without mistakes. We did not separately test its Korean writing.
Using Argon to get a fast first draft and handing the finishing to another model looks like a good fit.
Limits of this test
- One run per condition. Most of the community results are one or two runs too. Hard to generalize.
- Which video is "better" is my own visual judgment. Only frozen stretches were measured with a tool (ffmpeg freezedetect).
- The models wrote the code in one shot. Letting them see the render and revise could change the outcome.
- Prices are introductory. Argon's price doubles from December 1.
Watch the video
The video shows the results actually playing, along with other people's examples. The video is in Korean.
Sources
- Google, Introducing Gemini 4 Argon (2026-10-13)
- Google AI for Developers, Gemini 4 Argon model docs, Gemini API pricing
- Google DeepMind, Gemini model page (benchmark table), evaluation methodology
- Google Developers blog, Optimizing a 200,000-line Python codebase overnight with Gemini 4 Argon
- OpenRouter model pages: GPT-6.1 Sol, Claude Sonnet 5.5, Claude Opus 5.5
- X posts: @EnvolDev, @bridgemindai, @vib3coded, @notjazii
- BridgeMind, YouTube livestream